Keeping engineers building.
Not debugging
their environment.
How Efficient Computer Company turned engineering infrastructure from a daily distraction into the platform their team actually builds on.
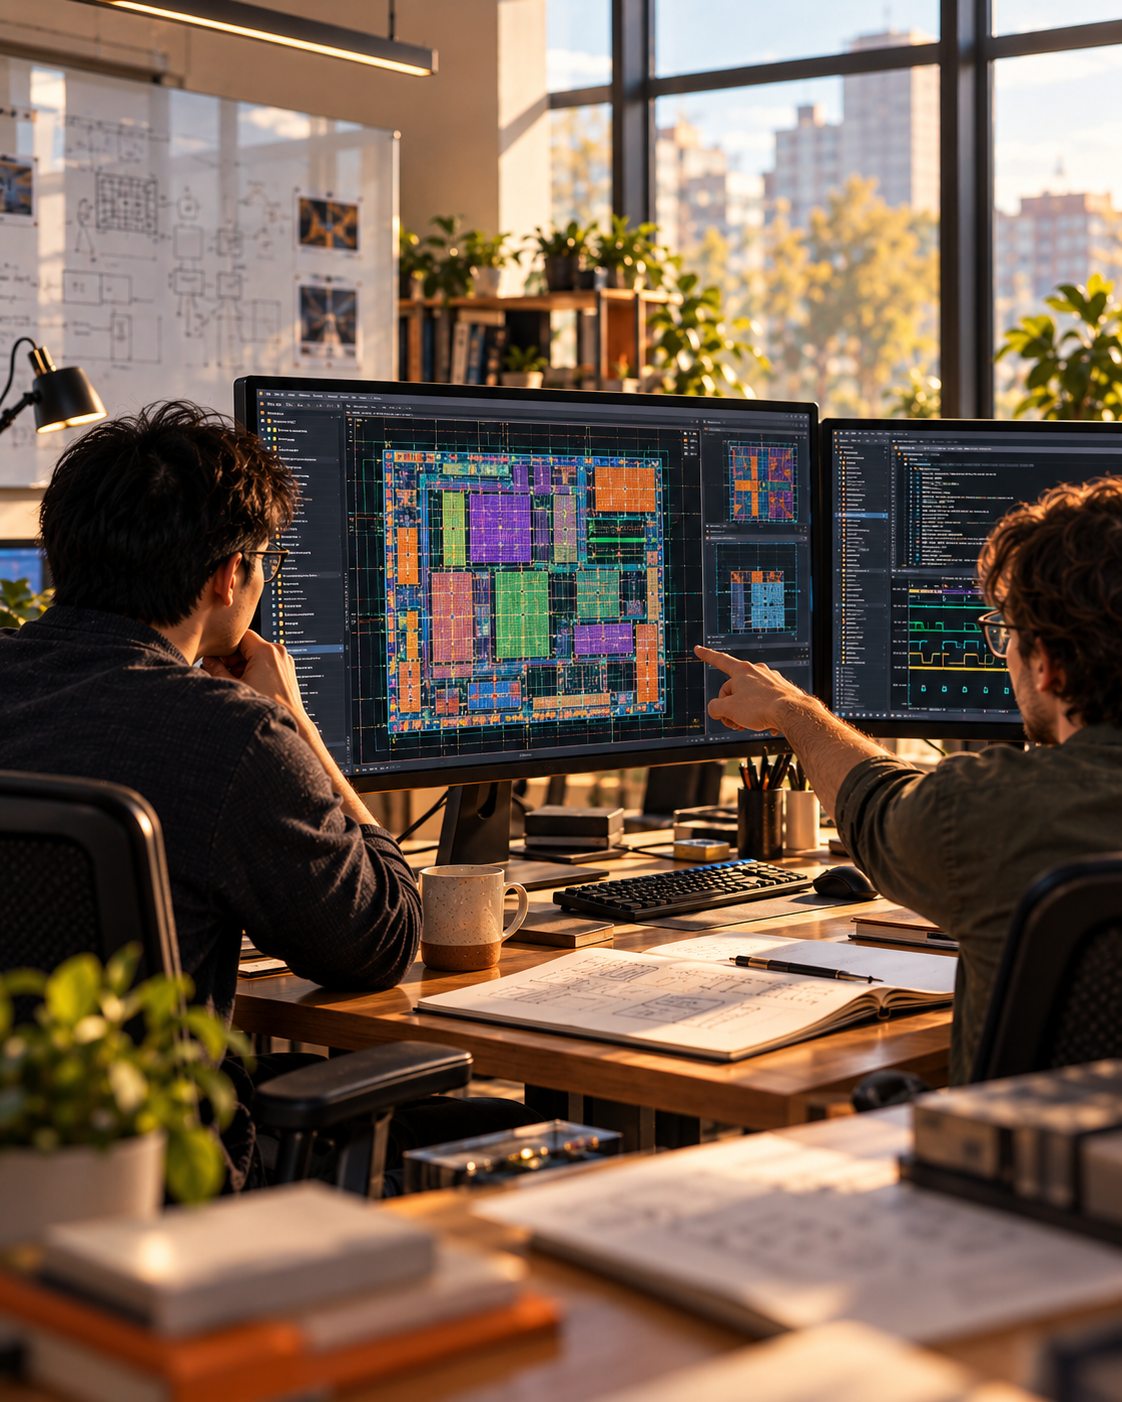
Every infrastructure issue is an engineer not building.
Efficient Computer Company is a chip design startup. Their engineers depend on always-available compute, developer VMs, continuous integration pipelines, a high-performance cluster for design workloads, shared storage that has to be there when it's needed. Infrastructure isn't a supporting function for them. It's the environment their entire R&D operation runs inside.
As they grew, so did the strain. Build jobs constantly queuing. Storage filling up at the worst moments. Logins breaking. Every one of these was a small emergency, because every one of them pulled a chip designer away from the work they were actually hired to do.
Hiring a full internal IT team wasn't the right move, the expertise they needed was too specialized and too varied. What they needed was a partner who could run the platform alongside them.
- 01 Scale compute and storage capacity ahead of engineering demand, not after it broke.
- 02 Get proactive monitoring and after-hours coverage without hiring an in-house team.
- 03 Have infrastructure experts embedded closely enough to fix things before engineers had to escalate.
Build the platform. Run it. Then show up in the same room.
We started with a full infrastructure migration, rebuilding the compute and CI environment on foundations sized for their real workload, not the patchwork they'd grown into. That alone significantly increased their capacity for both engineering compute and continuous integration.
From there, we took on the ongoing work: managing the engineering platform end to end, handling security and patching, tuning the compute cluster, onboarding new engineers, keeping storage ahead of demand. When they needed around-the-clock coverage, we added it. When they needed to scale ahead of a release, we scaled.
But the piece that mattered most, the one their CTO calls out specifically, is presence. Their engineers raise issues in a shared Slack channel and get real people responding in minutes, not tickets that sit in a queue overnight. That's the difference between an outsourced help desk and a team that's actually part of the operation.
Engineering platform management
Developer VMs, CI/CD pipelines, compute clusters, shared storage, the whole environment their engineers work inside.
Capacity planning & scaling
Ahead-of-demand scaling for compute, CI, and storage, sized for major releases before they happen, not after they hurt.
Identity & access management
Login systems, user provisioning, home directories, onboarding, the plumbing that determines whether new engineers are productive on day one.
24/7 monitoring & response
Continuous coverage so problems get caught before an engineer notices them, and handled before they escalate.
Real-time collaboration, in their Slack
Not a ticket queue. Not a support portal. Real engineers in the same channels as their engineers, fast, hands-on, with tickets created and work underway within minutes.
For a company where engineering uptime directly translates to business outcomes, having a dedicated infrastructure partner has been a game-changer.
The environment stopped getting in the way. Engineers started getting more done.
The queuing stopped. Storage stopped hitting limits at critical moments. Logins worked. Compute and CI capacity scaled meaningfully. The everyday infrastructure friction that had been quietly draining engineering productivity simply went away.
When they needed to scale ahead of a major release, we scaled. When they needed 24/7 monitoring, we brought it online. When something did go wrong, the response happened in their Slack in minutes, not in a ticket queue overnight.
For an R&D organization where every hour of engineering time is expensive and hard to replace, that's the whole business case.
Don't just take our word for it
As a semiconductor startup, our engineering team depends on always-available compute infrastructure, developer VMs, CI/CD pipelines, an HPC cluster for chip design workloads, and shared storage. As we grew, so did the strain on our systems. CI jobs were constantly queuing, storage was running out at the worst times, and we didn't have the internal IT resources to keep up with the infrastructure demands of a scaling hardware team.
Before working with Crafty Penguins, we were managing a patchwork of cloud infrastructure that wasn't purpose-built for our needs. We lacked proactive monitoring, had no after-hours support coverage, and every infrastructure issue, whether it was a downed runner, a full disk, or a broken login, pulled our engineers away from the work that actually matters.
Crafty Penguins changed that. They led us through a full infrastructure migration to bare metal, significantly increasing our compute and CI capacity. They managed a complex identity management transition that touched every engineer's login and home directory, and when that rollout hit bumps, their team was in our Slack channel working through issues alongside our people in real time. They've handled everything from GitLab administration and security patching to HPC cluster tuning, new employee onboarding, and storage management.
What I value most is the responsiveness and the feeling that they're genuinely part of our team. Our engineers raise issues directly in a shared Slack channel and get fast, hands-on support, often with tickets created and work underway within minutes. When we needed 24/7 monitoring coverage, they made it happen. When we needed to scale CI capacity ahead of a major release, they delivered.
For a company where engineering uptime directly translates to business outcomes, having a dedicated infrastructure partner that keeps pace with us has been a game-changer.
Working with similar organizations
Need your engineers building instead of debugging?
Crafty Penguins helps technical organizations run the engineering platforms their teams depend on, without building an internal IT department.