Skip to Content
Engagement type · Cluster Management

Managed clusters, kept current and healthy

Proactive management for your clusters. We handle upgrades, patching, observability, and incident response, so your team can focus on the applications running on top.

▲ crafty-penguins / what-we-do / engagement-types / cluster-management
What it is

What Cluster Management is

Cluster Management is our ongoing engagement for teams running production container platforms. Whatever you're running underneath, the operational work is similar: keep the platform current, keep the nodes healthy, keep incidents from becoming outages.

We handle the cluster-layer operations so your team doesn't have to. Version upgrades. Node patching. Storage integration. Observability stack tuning. Workload troubleshooting when a scheduling issue or a bad manifest brings something down. The unglamorous operational surface that makes the difference between a cluster that runs itself and one that quietly accumulates risk.

It works alongside server management, not instead of it. Our TLC Proactive Managed Services engagement keeps the machines underneath healthy: the OS, patching, backups, and monitoring on each physical or virtual server. Cluster Management picks up where that leaves off, running the cluster and the workloads on top. Most teams that run clusters pair the two together.

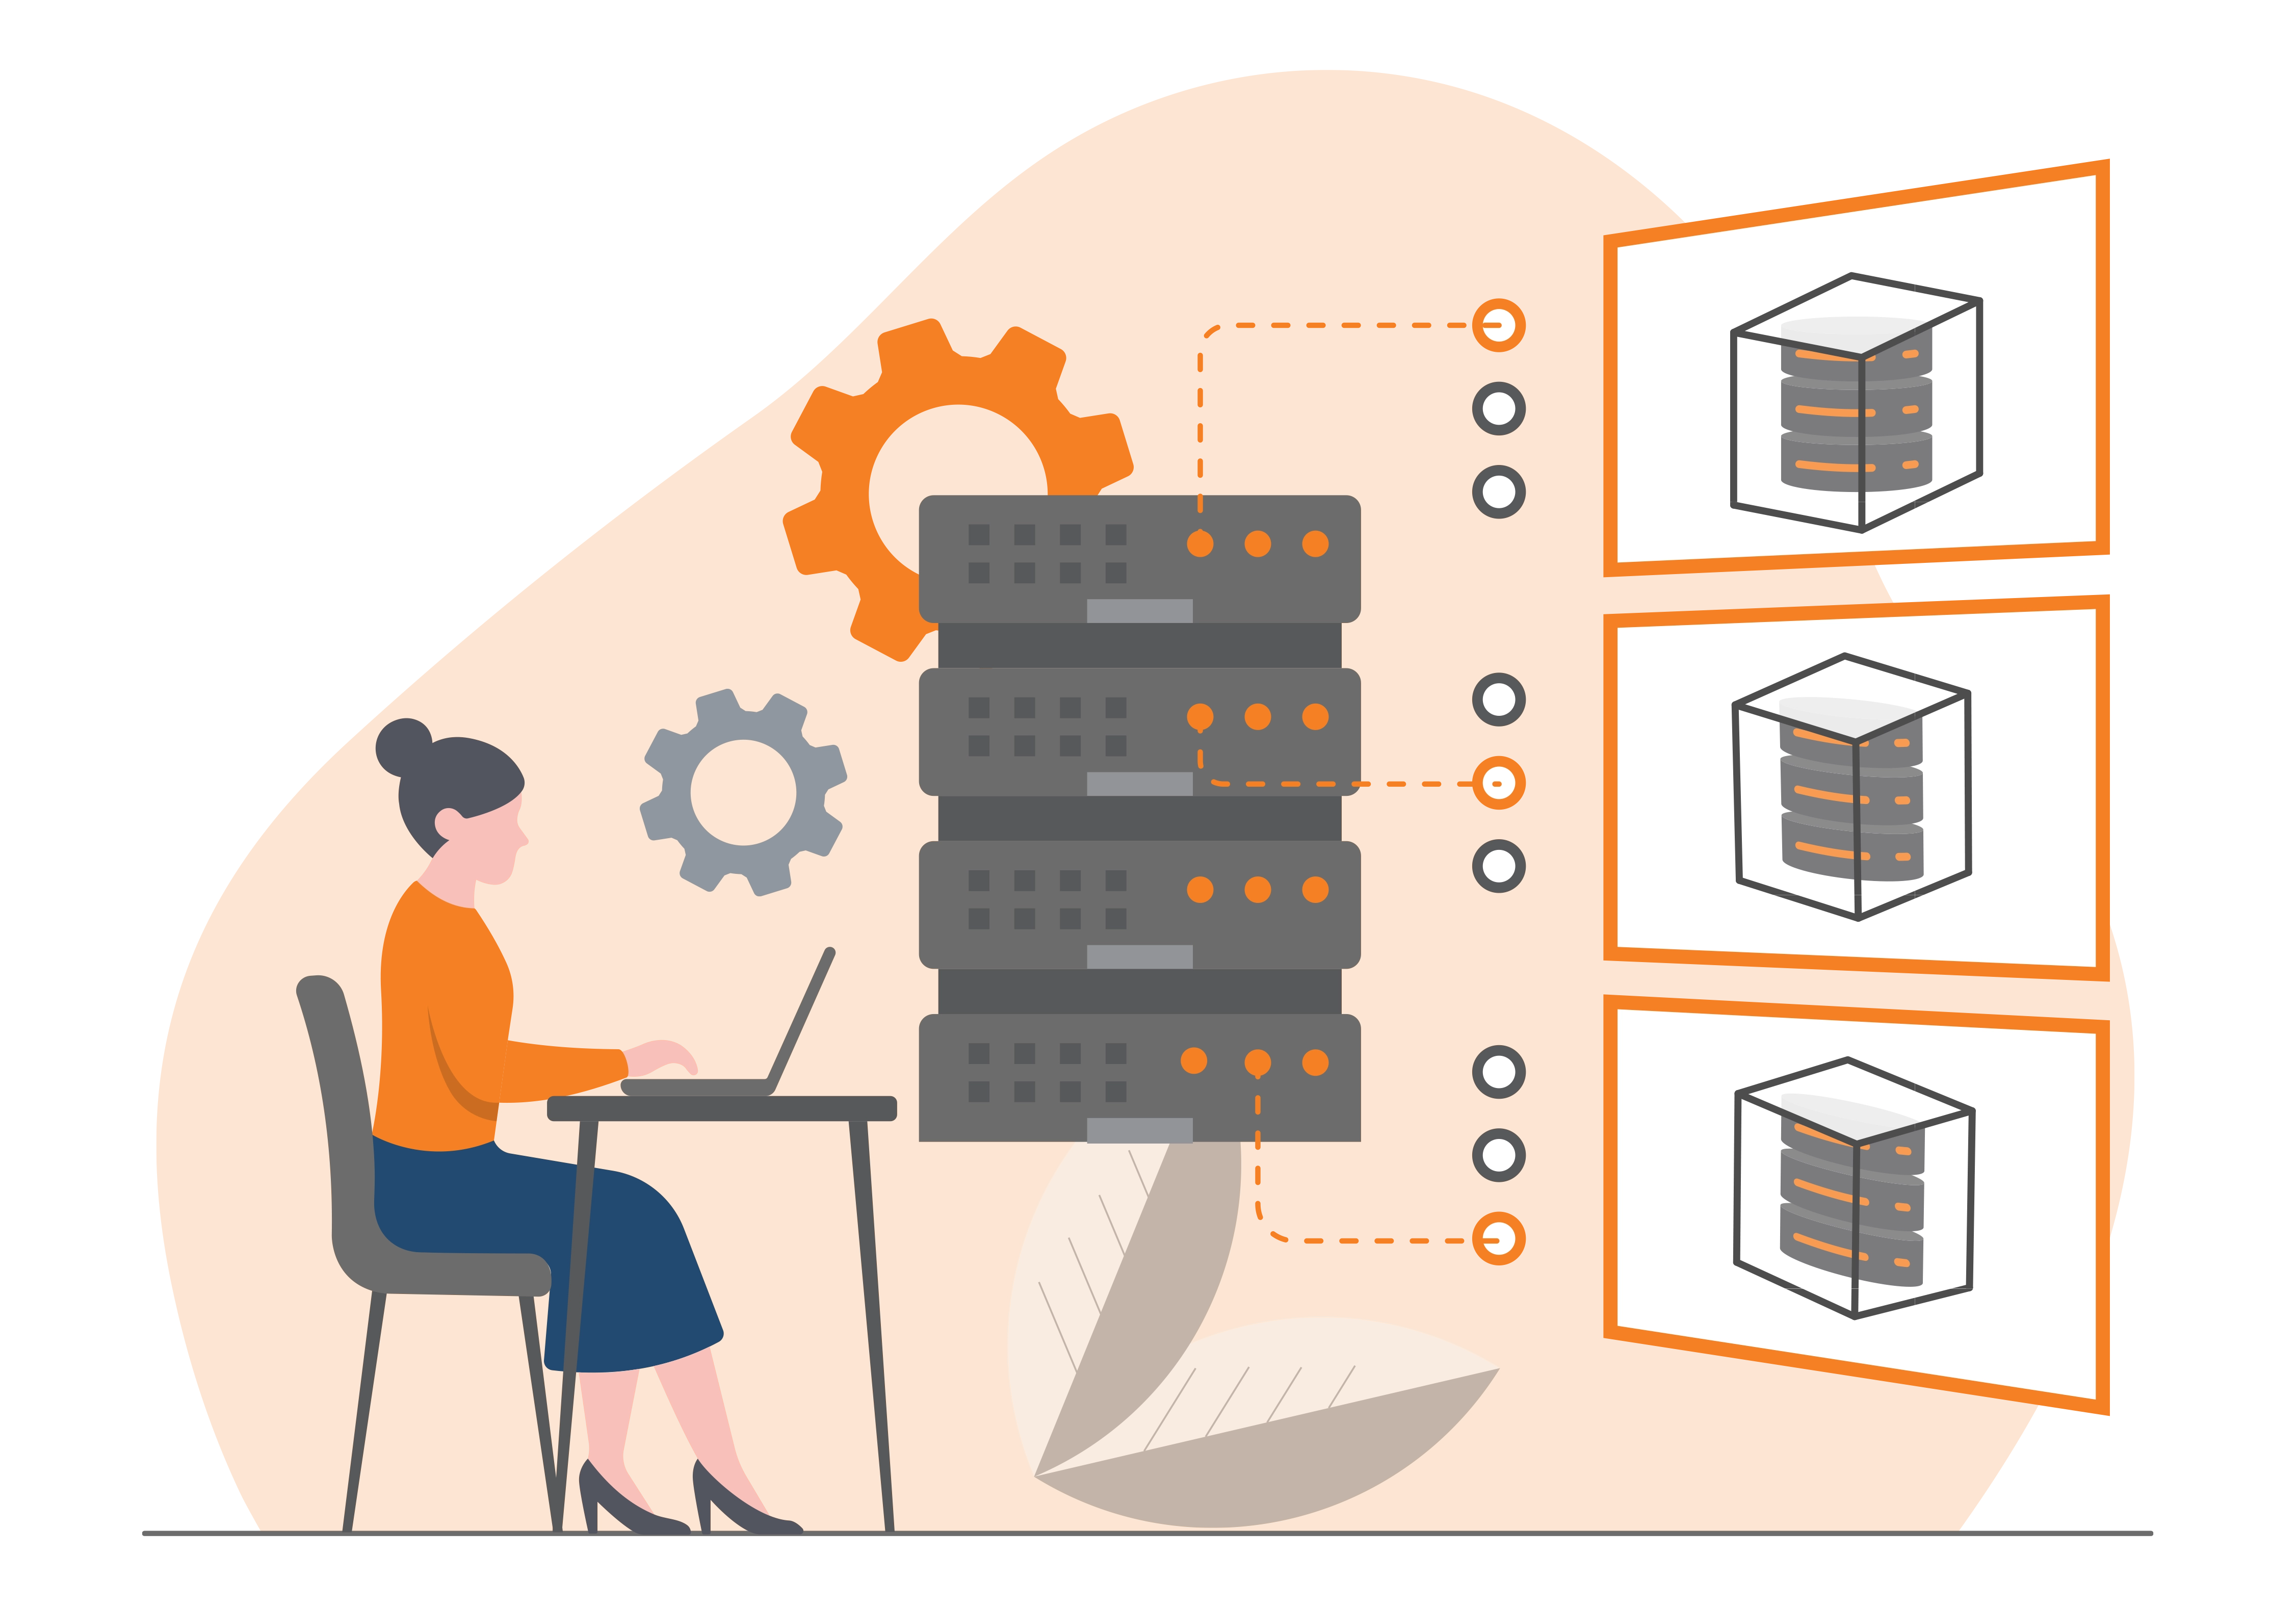
Cluster and container management
Two engagements, two layers. Here's where each one takes over:
Server / VM layer TLC Proactive Managed Services

Manages the machines your cluster runs on: OS patching, backups, monitoring, and maintenance for each physical or virtual server, whether or not it hosts a cluster.

Read about Proactive
Cluster layer Cluster Management This engagement

Runs the cluster on top of those machines: platform lifecycle and upgrades, node health, storage integration, observability, and the workloads scheduled across it.

What's in it for you

Why teams hand off the cluster layer

01

Your platform team gets its time back

  • Upgrades, patching, and node operations handled for you
  • Engineers focus on shipping applications, not babysitting the platform
  • No scrambling to keep pace with the release treadmill
Time back
02

Fewer incidents, caught earlier

  • 24/7 monitoring with alerting tuned to cut the noise
  • Problems triaged and worked before they become outages
  • Observability stack kept healthy so you can see what's happening
Fewer incidents
03

Senior platform expertise on tap

  • Engineers who run production clusters every day
  • No need to hire a scarce, expensive platform specialist
  • The same team learns your environment over time
Senior expertise
04

Stay current and supported

  • Clusters kept on vendor-supported versions, not drifting behind
  • Coordinated maintenance windows, no surprise downtime
  • Monthly reporting on patch compliance, upgrades, and incidents
Stay current
Who it's for

Who it's for

01
Your team ships applications on containers but doesn't want to run the cluster.
02
You need help with cluster upgrades, node operations, and platform observability.
03
Your organization is migrating between container platforms and needs experienced hands during the transition.
04
Your platform team is spread too thin to keep up with cluster upgrades, patching, and incident response.
What's included

What's included

The scope covers the operational surface of the cluster, with 24/7 monitoring and incident response built in.

Category 01

Cluster provisioning and configuration

✓ Provisioning clusters to an agreed baseline
✓ Control plane, networking, and access-control configuration
✓ Managed cluster configuration for consistency and DR
✓ Declarative and GitOps-style configuration workflow support
Category 02

Upgrades, scaling, and version alignment

✓ Upgrades aligned to vendor-supported versions on an agreed cadence
✓ Node scaling recommendations and capacity guidance
✓ Keeping cluster components on compatible, aligned versions
✓ Coordinated maintenance windows for platform changes
Category 03

Storage integration and performance tuning

✓ Storage driver and integration operation and troubleshooting
✓ Persistent volume and storage lifecycle management
✓ Investigation of stuck mounts, pending volumes, and attachment issues
✓ Performance tuning at the cluster and storage interface
Category 04

Node health monitoring and OS patching

✓ Continuous node health monitoring (agent status, resource pressure, disk)
✓ Scheduled OS patching with reboot coordination
✓ Cordon and drain procedures for node lifecycle work
✓ Escalation when hardware or hypervisor intervention is needed
Category 05

Backup and recovery workflow oversight

✓ Oversight of cluster and workload backup workflows
✓ Verifying backups run and remain recoverable
✓ Coordinating restore procedures when needed
✓ Documenting recovery runbooks for the platform
Category 06

Cluster health monitoring

✓ Metrics, logging, and alerting stack operation
✓ 24/7 monitoring with alert tuning and noise reduction
✓ Dashboard maintenance for platform visibility
✓ Monthly operational reports covering patches, upgrades, and incidents
What you'll provide

What you'll provide

Successful cluster management is a two-sided engagement. Here's what we'll need from your side.

Required
Cluster access

VPN, bastion, accounts, and access permissions needed to operate on the clusters.

Required
Infrastructure coordination

Ability to coordinate actions with your infrastructure team (vSAN, hypervisor, hardware) when needed.

Required
Maintenance approvals

Advance approval of maintenance windows and an up-to-date escalation contact list.

Required
Target architecture

Agreement on cluster architecture (node roles, HA expectations) and observability retention targets during onboarding.

Cluster Management in action

All success stories
Other engagements

Explore our other engagements.

There are a few different ways to work with us. Here are the other engagements you can explore.

Start the conversation

Ready to hand off your clusters?

A 30-minute conversation is enough for us to understand your platform, walk through what we'd cover, and give you an honest read on scope and pricing.