Capacity, not headcount
Linux engineering hours without opening a requisition
You own the infrastructure and the decisions about it. We bring the Linux engineering depth to carry them out: the recurring maintenance your team never gets to, the specialist work that cannot justify a full-time hire, and the projects that keep sliding to next quarter. Who does what is written down, and the architecture stays yours.
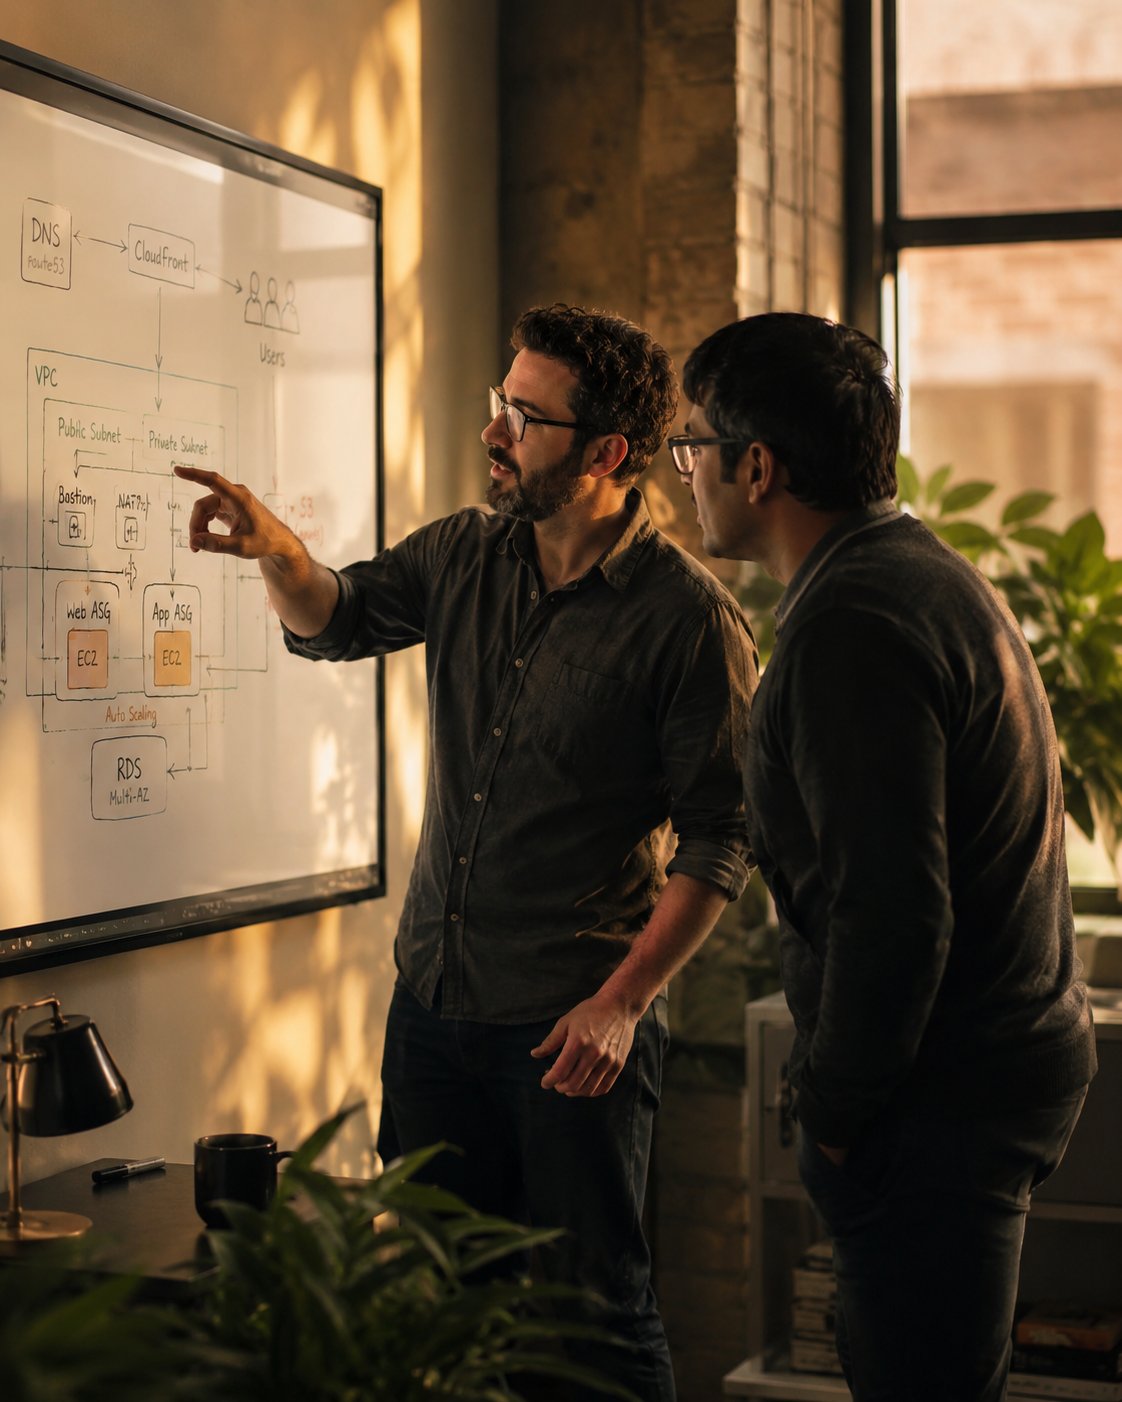
Linux engineering hours without opening a requisition
Kubernetes, storage, clustering and virtualization depth on call
Patching, upgrades and monitoring work that keeps sliding
Defined responsibilities, with the decisions still made by your team
Somewhere to send the problem that is past your team's depth
The gaps we are usually asked to fill alongside a team that already exists.
Reduce downtime risk on systems where every minute of outage carries compliance exposure, public impact, or constituent trust.
Learn more >
Cutovers, hyperscaler moves, and tenant-safe maintenance windows that don't become surprise downtime for paying customers.
Learn more >
When your team can run a Linux box but can't run twelve, or thirty, or three hundred, senior Linux bench capacity without a full-time hire.
Learn more >
Modernizing aging Linux systems without disrupting transaction-processing windows or core banking schedules.
Learn more >
Tested failover, backup integrity, and recovery objectives that hold up under examiner scrutiny.
Learn more >
Visibility across heterogeneous Linux environments so incidents surface before outages show up for users, citizens, or downstream partners.
Learn more >
You do not need another vendor slide. You need an estate you can explain to the board without guessing.
Capacity, coverage, and an estate that is written down.
Senior Linux engineers working alongside your staff, so you add capability without adding a role you then have to retain.
Kubernetes, storage, clustering and virtualization expertise available when the work needs it, instead of hired for the one project that needed it.
Monitoring, patching and routine Linux administration handled on a schedule, which frees your staff for the work only they can do.
Engineering capacity for the upgrades and migrations that keep slipping because nobody has a free week.
Responsibilities set out in writing. We operate what we are asked to operate, and the architecture and roadmap remain yours.
Infrastructure reviews, documentation and reporting that show server health, lifecycle status and what still needs attention.
Deferred maintenance and legacy systems worked through on a plan, rather than carried until something forces the issue.
Real engagements, real outcomes.
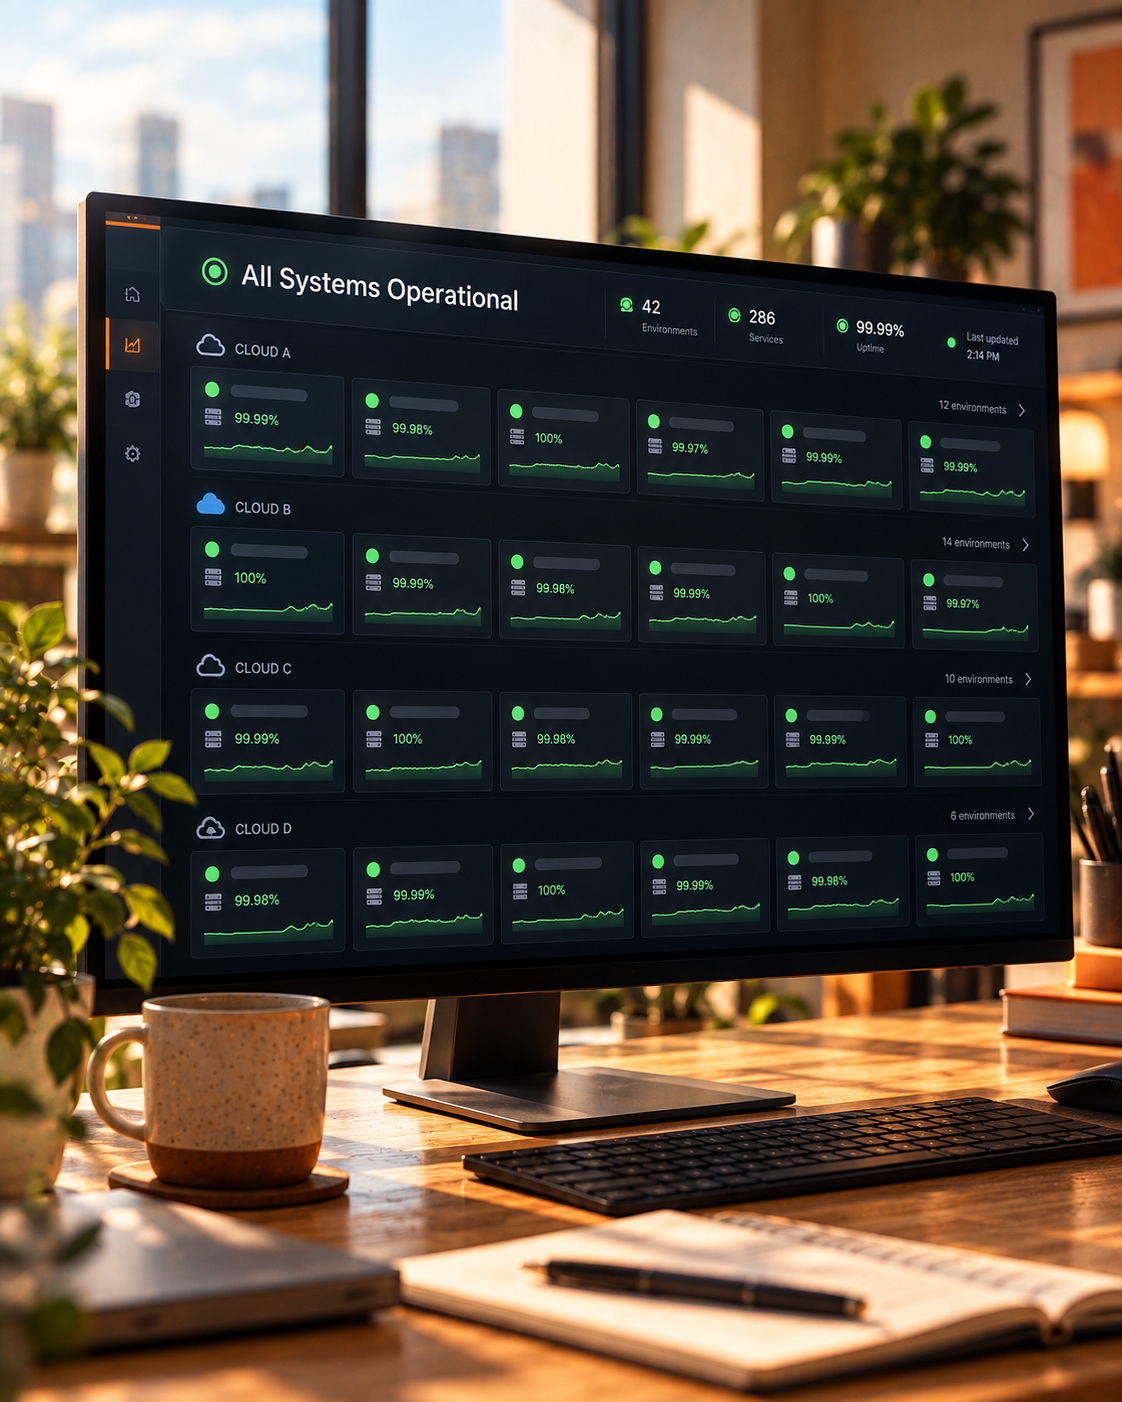
How Elite Digital handed off their multi-cloud server operations to a team their clients would never see, and never need to.
How the American Dairy Goat Association migrated off AWS, upgraded Oracle, and got back to their mission, on a non-profit budget.
How Efficient Computer Company turned engineering infrastructure from a daily distraction into the platform their team actually builds on.
How Unite Communications got the specialized infrastructure expertise of a full IT team, for less than the cost of a single in-house hire.
How Follosoft stopped firefighting Linux infrastructure and got back to building their field-operations platform.
How 1WorldSync handed Linux operations to Crafty Penguins, and got their focus back.
How Crafty Penguins delivered a fully production-ready, high-availability, multi-data-center platform for a US commercial bank, from zero footprint to documented handover.
How Crafty Penguins brought a US commercial bank's enterprise Linux fleet to a documented, high-90s compliance score, server by server, control by control.
What this work looks like in practice.
A short call with an engineer. Tell us where your team is stretched and we will tell you which parts we would take on and which you should keep.
Conversation first, scope second. No pressure.